On-Device AI: What Runs Locally on Your Phone or Laptop Now (and Why It Matters)
For the last few years, "AI" in a consumer product has mostly meant a round trip to a data center — your phone or laptop sends a request to the cloud, a large model somewhere in a server farm processes it, and the response streams back. That's still true for the biggest, most capable models, but a real and increasingly important shift is happening in parallel: genuinely useful AI features now run entirely on-device, on the same chip that's already in your pocket or your laptop bag, with no network round trip at all.
What "On-Device" Actually Means
Running an AI model on-device means the entire inference process — taking your input and producing an output — happens using the local processor's own compute resources, without sending any data to an external server. This is a meaningfully different architecture from cloud AI, and it requires models specifically built or shrunk to fit within a phone or laptop's memory and power constraints, since the massive models behind the most capable cloud chatbots are far too large to run on a phone's limited RAM even if the phone had unlimited processing time to spare.
The hardware that makes this possible is the NPU (neural processing unit) — a dedicated chip component built specifically for the matrix-multiplication math that AI models rely on, distinct from the CPU (general computing) and GPU (graphics, though also usable for AI math). Apple's Neural Engine, Qualcomm's Hexagon NPU in Snapdragon chips, and the NPUs inside Windows "Copilot+ PC" hardware all serve this same basic role: running AI workloads far more power-efficiently than forcing the same computation through a general-purpose CPU, which is why on-device AI became genuinely practical for phones and laptops only once NPUs became a standard, powerful component rather than a niche addition.
Why Run AI Locally At All, If the Cloud Is More Capable?
Cloud models will generally remain more capable for a while — they can be far larger, since a data center doesn't have a phone's battery or memory budget, and they're easier to update since there's no need to push a model update to millions of individual devices. But on-device AI wins on three things cloud AI structurally can't match: latency, privacy, and offline availability. Processing entirely on the device eliminates network round-trip time, which matters for real-time features like live transcription or camera-based effects that need to respond within milliseconds rather than the noticeable lag of a cloud round trip. Privacy is arguably the bigger draw for certain use cases — data that never leaves the device can't be intercepted in transit or retained on a company's servers, which matters for something like reading and summarizing your personal messages or photos, categories of genuinely sensitive personal data that many users are uncomfortable sending to any cloud service regardless of a company's stated privacy policy.
Offline availability is the most straightforward benefit: an on-device feature keeps working on a plane, in a basement with no signal, or anywhere else connectivity is unreliable, while a cloud-dependent AI feature simply stops functioning the moment the network connection does, regardless of how good the underlying model is.
What's Actually Running On-Device Today
The most mature on-device AI features tend to be narrower and more specialized than a general-purpose chatbot: on-device transcription and dictation, computational photography features like subject isolation and portrait-mode processing, real-time language translation without an internet connection, and increasingly, smaller general-purpose language models capable of basic writing assistance, summarization, and simple Q&A entirely offline. Apple's on-device Apple Intelligence features (notification summaries, Writing Tools, some Siri request handling) and Google's on-device Gemini Nano model on Pixel phones represent the current state of the art for squeezing genuinely useful general-purpose language capability into a phone's power and memory budget, though both still route more complex requests to cloud models when the on-device model isn't capable enough for the task — a hybrid approach that's become the practical norm rather than a pure on-device-only or cloud-only design.
The Real Tradeoff: Capability Versus Everything Else
Smaller on-device models are, unavoidably, less capable than their cloud counterparts at complex reasoning, broad general knowledge, and nuanced creative writing — a gap that's narrowing as on-device models improve, but remains real today. This isn't a flaw to be engineered away entirely; it's an inherent tradeoff of fitting a model into a few gigabytes of memory running on battery power instead of a data-center rack with effectively unlimited compute. The practical implication for users is that on-device AI features tend to be most reliable for well-defined, narrower tasks (transcribe this, summarize this notification, isolate this subject in this photo) and less reliable for open-ended requests that benefit from a much larger model's broader training and reasoning capacity — a distinction that matters when comparing how different AI assistants and agentic tools actually perform across different kinds of tasks.
Why This Matters for Buying a Phone or Laptop
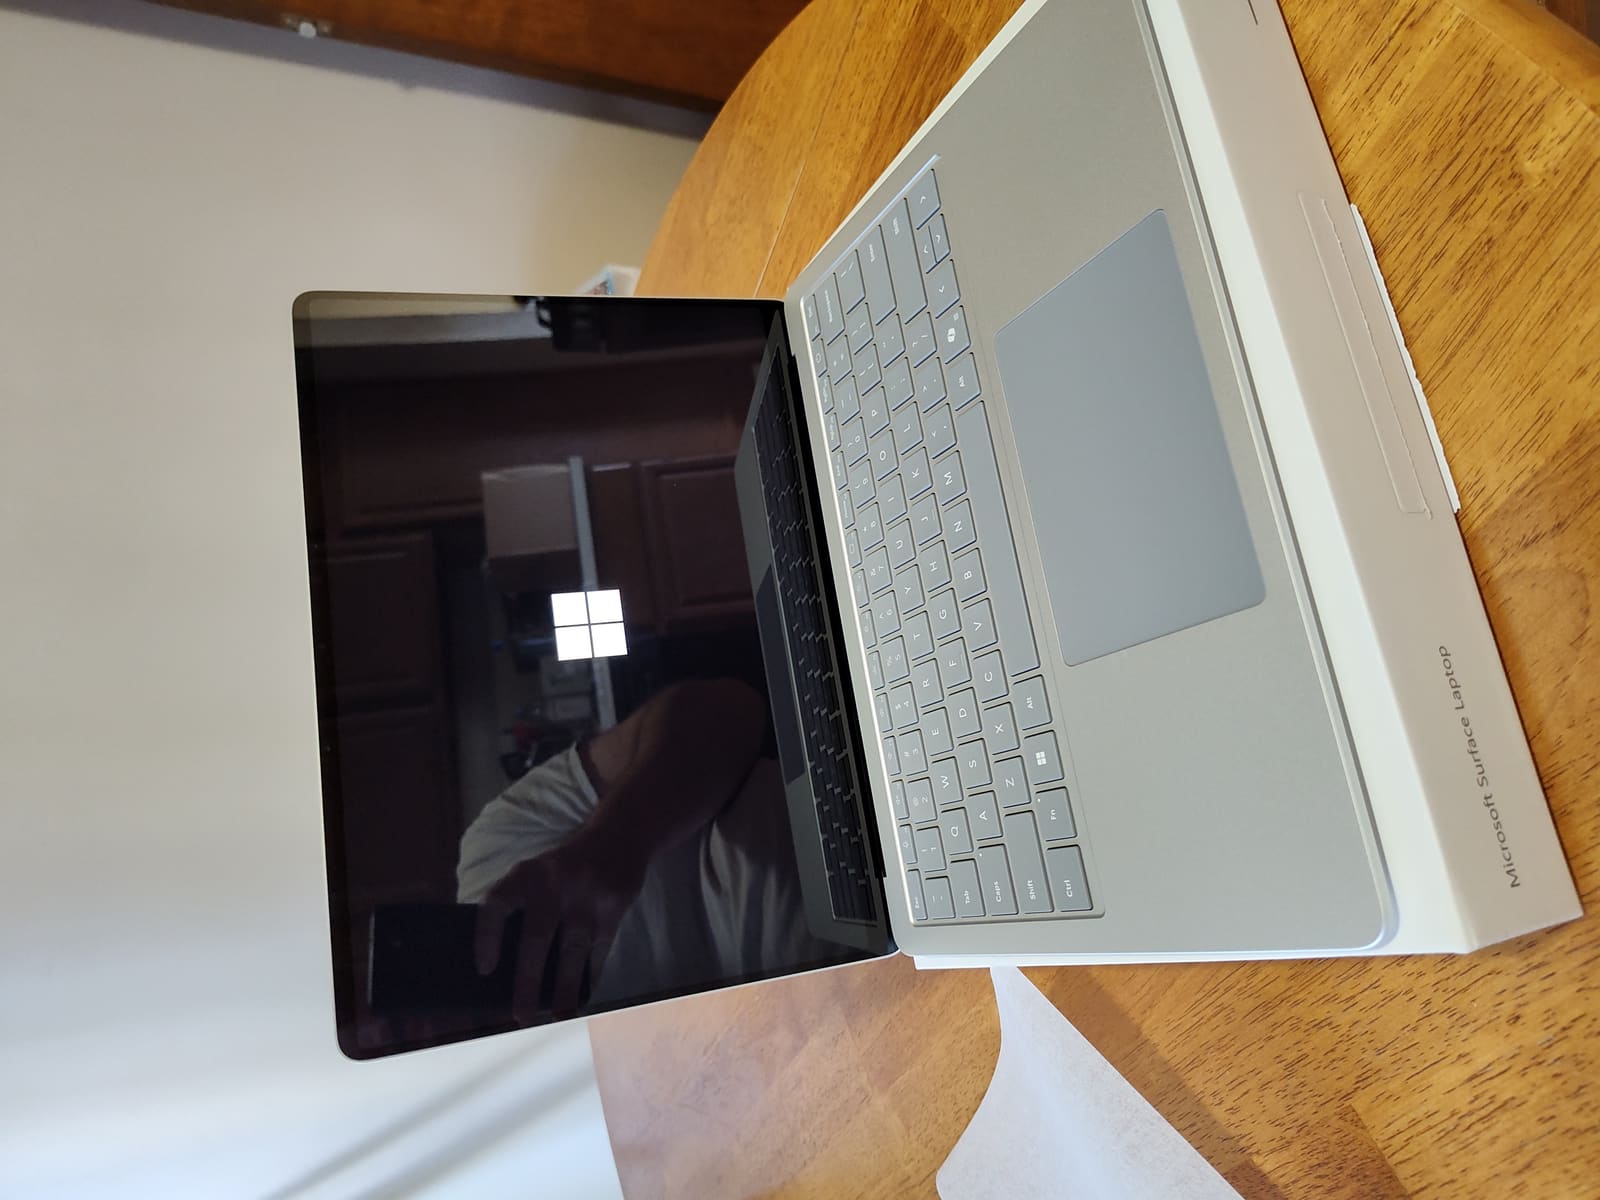
On-device AI capability has become a genuine hardware differentiator, not just a software feature you can add later. A phone or laptop's NPU throughput directly determines which on-device AI features it can run at all, and at what speed — which is why Microsoft's Copilot+ PC certification requires a minimum NPU performance threshold, and why older phones and laptops without a sufficiently powerful NPU simply can't run certain newer on-device AI features even after a software update, regardless of how much the rest of the hardware is upgraded. This is a genuinely new category of hardware obsolescence: a perfectly capable laptop for traditional computing tasks that's excluded from a manufacturer's on-device AI feature set purely because its NPU falls below the required performance bar, similar in spirit to how Copilot+ PC hardware requirements created a hard cutline for which existing Windows laptops could and couldn't run the new AI features Microsoft built around dedicated NPU hardware.
Where This Is Heading
The likely direction isn't on-device AI fully replacing cloud AI, but a continued, more seamless hybrid: routine, latency-sensitive, or privacy-sensitive tasks handled locally by an increasingly capable on-device model, with genuinely complex requests transparently routed to the cloud when the local model recognizes it's out of its depth. As NPUs get more powerful and on-device models get more efficient at packing capability into a smaller footprint, the line of what can run locally will keep moving — but the fundamental tradeoff between a device's local compute budget and a data center's effectively unlimited one isn't going away, which means the hybrid approach, not a purely local or purely cloud one, is likely to remain the practical default for the foreseeable future.